What is SAIL?
SAIL audits whether the state representations used in offline reinforcement learning for sepsis treatment already encode the treatment action they're meant to precede. It proves two mechanisms by which this happens, quantifies both on an independent MIMIC-IV extraction, and pre-registers a falsifiable test for the one claim that isn't provable in closed form.
What's actually new here?
The treatment-dependence of the SOFA cardiovascular subscore is not a secret — it's documented in the clinical literature (Vincent et al., 1996) and known to clinicians who use the score daily. The contribution isn't discovering that dependence. It's showing that offline sepsis-RL pipelines treat this therapy-dependent score as a valid pre-decision state feature without accounting for that dependence — and proving it formally rather than flagging it informally. Of the two theorems, Theorem 2's exact reconstruction result — that removing the subscore alone doesn't remove the information, because the total is a deterministic sum that lets it be reconstructed by subtraction — is the least clinician-known and most novel single finding: the failure mode a clinically-informed intuition ("just drop the risky field") would miss entirely.
Why was it created?
Offline sepsis-RL research — the "AI Clinician" and its descendants — evaluates policies against retrospective data using state representations built substantially from the SOFA score. If that state is already a near-deterministic function of the treatment it's supposed to precede — treatment-confounded by construction, not through physiology — off-policy value estimates in this literature should be read with that in mind. This project does not evaluate or discredit any specific published policy — it quantifies a property of a commonly used state construction.
Research question
Does a SOFA-based state representation in offline sepsis-RL encode the prior treatment action it precedes, undermining the assumption the framework depends on?
Scientific contribution
- Two mathematically proven treatment-confounding mechanisms (non-identifiability, algebraic reconstructibility) — see Terminology for why this is confounding, not ML-sense leakage
- A causal-graph formalization explaining why predictability alone can't settle whether the AUROC gap reflects these mechanisms specifically, or ordinary treatment persistence
- An independently re-extracted, five-times-reproduced empirical audit — including three real pipeline bugs found, diagnosed, and fixed in the open
- A pre-registered, falsifiable decision procedure for the one open claim
Open science
Every extraction query, the full analysis notebook, and the complete bug-fix history are public. Patient-level MIMIC-IV data is not — see DATA_ACCESS.md for the governance policy this project holds itself to.
Team
Built across disciplines. SAIL brings together the perspectives needed to test the system around a model, not only the model itself.
 Part of the MIT Critical Data project family
Clinical research
Clinicians and health researchers
Define meaningful failure modes, intended use, and the realities of care.
Technical practice
ML practitioners and engineers
Build evaluators, reproducible pipelines, and evidence that can be inspected.
Public accountability
Community reviewers
Bring local context, lived experience, and challenge to what counts as readiness.
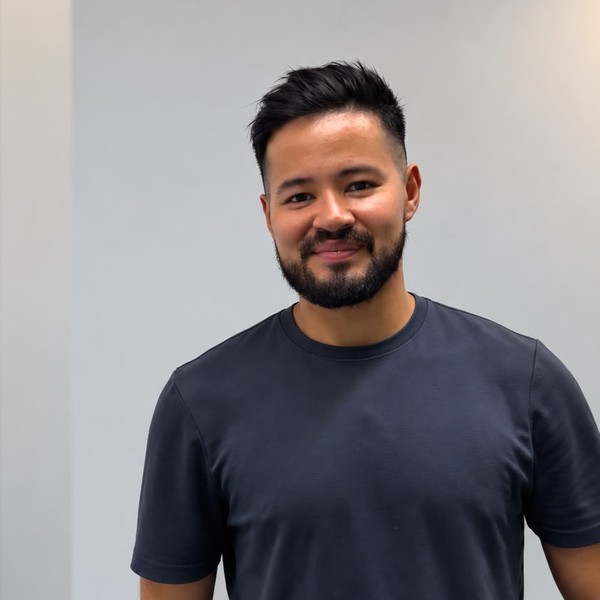
Photos and LinkedIn links for confirmed team members appear below. Further profiles, links and contact details will be added as the project owners confirm additional names and public information to display.
Mohammad Shahin
Project Lead — MIT Laboratory for Computational Physiology; Boston University School of Public Health
View LinkedIn →
Community & related work
Bodhi
BODHI is an engineering framework for curiosity driven and humble AI in clinical decision support. The courage to ask before answering.
Visit Bodhi →DOJO
DOJO is an open, community-driven platform for adversarial evaluation of clinical AI systems.
Visit DOJO →Placeholder
Project name
One-line description of the related lab project.
Contact & collaboration
For questions, corrections, or collaboration inquiries, open an issue on the GitHub repository.
SAIL is open source (MIT licence) and built in the open: code, results and decisions are reviewed in public pull requests.